Your Headless Ecommerce Stack Works. Now What Breaks in Production?
7 production problems to solve before your headless ecommerce stack starts handling real customers and orders.
A headless ecommerce build can look production-ready surprisingly early. Products load correctly, editors can publish content, customers can add items to their carts, and checkout works exactly as expected during testing.
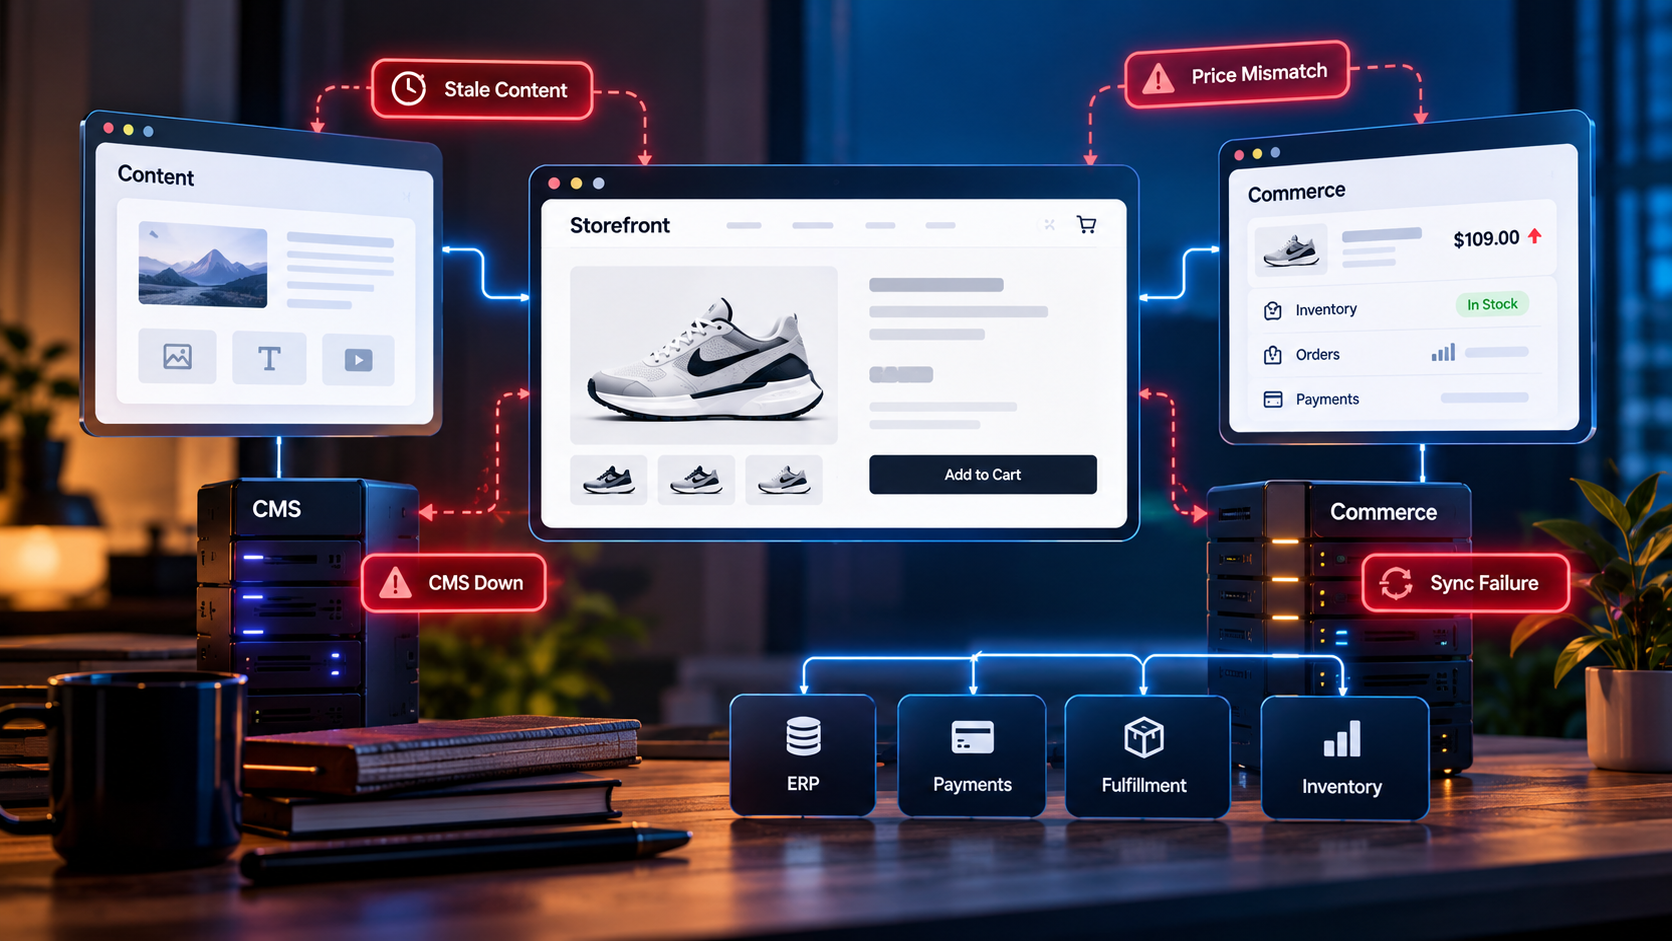
The harder problems usually appear when those independent systems begin changing at different times. A price changes, a product disappears, a webhook fails, or cached content remains visible longer than expected.
When Medusa handles commerce, Sanity or Strapi manages content, and Next.js brings everything together, these seven production problems are worth solving before the architecture starts handling real customers and orders.
The CMS publishes, but the storefront still shows old content
Publishing content does not automatically make the storefront current. Sanity or Strapi may return the updated content immediately while Next.js, a CDN, or another caching layer continues serving an older response.
Editor
   ↓
Sanity / Strapi
   ↓
Publish
   ↓
Webhook
   ↓
Next.js
   ↓
Revalidate affected content
A better approach connects publishing with targeted cache invalidation. Instead of refreshing the entire storefront, identify which page or cached data depends on the changed content and revalidate only what needs updating.
For teams planning Sanity development, this publishing flow deserves attention early because content modeling alone does not determine how quickly a published change becomes visible to customers.
The CMS references a product that no longer exists
A campaign page may reference a commerce product by ID, but that relationship exists across two independent systems. If someone later removes that product from Medusa, the CMS reference may still remain.
Summer Collection
      │
      ├── Hero
      ├── Campaign Copy
      │
      └── Featured Product
               │
               └── product_123
The storefront should therefore treat external references defensively. When product_123 cannot be found, it might hide the product card, show an appropriate fallback, or continue rendering the remaining campaign content.
This distinction matters because an external product ID is not the same as a database relationship controlled by one application. Products get discontinued, imports fail, identifiers change, and storefront code should expect those situations.
The product page and checkout disagree on price
Imagine a product page caches an $89 price, then Medusa receives a new $109 price several minutes later. A customer could see $89 on the page but $109 during checkout.
10:00 → Product price: $89
10:01 → Storefront caches $89
10:05 → Price changes to $109
10:07 → Product page still shows $89
10:08 → Checkout uses $109
The problem is not caching itself. The problem is treating campaign content, product descriptions, prices, and inventory as though they all have the same freshness requirements and the same business consequences.
A better question is not simply, “How long should this page be cached?” Ask how stale each individual type of information can safely become before the difference affects customers or operations.
Content and transactional data need different rules
A campaign headline remaining unchanged for several minutes may be harmless, while stale pricing or inventory can affect purchasing decisions. Cache and revalidation rules should reflect that difference instead of treating everything equally.
A webhook arrives twice
Webhooks are useful for connecting independent systems, but production code should not assume every event arrives exactly once. Temporary network problems or retries can cause the same event to reach an endpoint again.
Webhook received ↓ Verify request ↓ Read event ID ↓ Already processed? /
Yes No ↓ ↓ Ignore Process ↓ Record event ID
A safer webhook handler checks a stable event or transaction identifier before processing the request. If the event has already completed successfully, receiving it again should not create duplicate records or actions.
The same thinking applies when processing fails. Teams should know whether events retry automatically, how failed events can be replayed, and where someone can see that synchronization has stopped working.
The CMS goes down during checkout
A useful production test is asking what happens when the CMS becomes unavailable for ten minutes. If commerce services remain healthy, an editorial system outage should not automatically stop customers from completing purchases.
             Storefront
            /          \
           /            \
    Editorial          Commerce
      Content            Data
         ↓                ↓
  Sanity / Strapi       Medusa
                           ↓
                  Payment / Fulfillment
Cached editorial content may continue serving while publishing or uncached experiences become temporarily unavailable. Keeping commerce separate prevents a content-management failure from unnecessarily becoming a transaction failure at the same time.
This matters when planning Strapi development because teams may control the CMS application, database, deployment, APIs, webhooks, and infrastructure, making failure boundaries an important architectural decision rather than only a hosting concern.
The commerce backend goes down, but the CMS remains healthy
Now reverse the situation. Sanity or Strapi, Next.js, and the CDN remain available, but Medusa cannot respond. Editorial pages may continue working while live commerce functionality becomes partially or completely unavailable.
Editorial pages             ✓
Blog                        ✓
Cached product content      ✓

Live pricing                ?
Availability                ?
Add to cart                 ✕
Checkout                    ✕
Customer account            ?
This is why each storefront feature should have a clear dependency map. A buying guide should not require a healthy commerce API unless it genuinely needs live commerce data to render correctly.
When custom ERP, POS, PIM, WMS, payment, or fulfillment integrations are involved, Medusa development should account for those dependencies and define what customers experience when one of them becomes unavailable.
Think in failure boundaries, not only integrations
An architecture diagram should show more than which systems exchange data. It should also help the team understand which customer experiences stop working when a particular API, database, integration, or external service fails.
The integration fails quietly
Some production failures never create an obvious error page. An ERP-to-Medusa inventory sync can stop while the storefront, ERP, and commerce backend all remain online and appear healthy individually.
ERP
 ↓
Inventory sync
 ↓
Medusa
 ↓
Storefront
If that synchronization normally runs every five minutes and silently stops at 02:15, customers may continue seeing increasingly outdated inventory even though monitoring shows that all major applications remain available.
That is why integration health should be treated as application health. Teams should monitor successful synchronization time, failed records, retry counts, webhook failures, queue depth, API latency, and the age of operational data.
A practical production check before launch
A production review does not need to become a large architecture exercise. It should simply confirm who owns important information, how fresh that information must remain, and what happens when dependencies fail.
| Question | Why it matters |
|---|---|
| Who owns each important field? | Prevents conflicting updates |
| What data can be cached? | Improves performance safely |
| How stale can each value become? | Connects freshness with business risk |
| What triggers revalidation? | Keeps published content current |
| Can a webhook run twice safely? | Protects against duplicate processing |
| What happens when a reference disappears? | Prevents avoidable page failures |
| What happens when the CMS fails? | Defines the content failure boundary |
| What happens when commerce fails? | Defines the transaction failure boundary |
| Can failed integrations retry? | Helps temporary failures recover |
| Can stale synchronization be detected? | Finds silent failures earlier |
| Does checkout depend on the CMS? | Removes unnecessary dependencies |
The exact answers will vary between a smaller DTC store and a retailer connected to ERP, PIM, WMS, POS, and fulfillment systems. What matters is making those decisions deliberately before customers discover them.
Production readiness is mostly about the unhappy path
A successful demo proves that Medusa, the CMS, and the storefront can communicate when everything behaves normally. Production readiness requires knowing what customers experience when one of those connections becomes slow, stale, unavailable, or inconsistent.
Before launch, deliberately stop the CMS, duplicate a webhook, remove a referenced product, change a cached price, interrupt an inventory sync, and make a commerce request fail. Then observe what actually reaches customers.
Those tests reveal whether the architecture merely works or can recover when something goes wrong. In a headless ecommerce system, that difference often matters more than another successful checkout under perfect test conditions.